Tubefalire Explained: Understanding Digital System Failures
Tubefalire Explained helps readers understand the possible causes of digital system failures, technical errors, and unexpected performance problems. In today’s technology-driven world, network disruptions, server overloads, software conflicts, and data integrity issues can affect how digital platforms operate. Understanding Tubefalire, its potential warning signs, and related technical problems can help users and developers identify issues and explore effective solutions. This guide covers common causes, troubleshooting methods, recovery strategies, and practical prevention techniques to improve digital system reliability.
Your upload hits 87% and then freezes. The app doesn’t crash. The progress bar just sits there. Many people now call this moment Tubefalire. The word describes a chain breakdown inside digital system failures.
This guide explains the Tubefalire meaning, the causes, the fixes and the prevention steps. You will learn the common causes of digital failures. You will also get clear Tubefalire Explained. Every section uses plain words and short sentences.
What Is Tubefalire in Digital Systems?
Tubefalire Explained? It is a pattern of digital system failures where data stops moving through connected layers. Networks, servers, devices and software all play a part. When one layer slips, the whole chain stalls. Tubefalire isn’t an official industry standard. IT teams usually call the same event a system malfunction or a partial outage.
The Tubefalire meaning gets clear with a water pipe picture. Water needs pressure and a sound pipe. Data needs bandwidth and healthy systems. So what does Tubefalire mean in digital systems? It means the flow breaks before the job ends. The system rarely dies fully. It stalls halfway.
Where Does Tubefalire Commonly Occur?
Data fails wherever it travels. Web apps, SaaS platforms and cloud storage tools top the list. Streaming services and mobile apps built on API communication follow close behind. Enterprise dashboards also suffer when many services feed one screen. Strong digital infrastructure lowers the risk in all of these places.
Picture a 500MB video upload that stops at 87%. Your account works. Your internet works. Yet the transfer never ends. That partial interruption is the classic sign of Tubefalire errors. The table below shows other common spots.
| Environment | Typical Symptom |
| Cloud storage | Sync stops halfway |
| Video streaming | Endless buffering |
| Mobile apps | Frozen screens during refresh |
| Enterprise dashboards | Blank or partial charts |
| APIs | Incomplete responses |
11 Common Causes of Tubefalire in Digital Systems
The Tubefalire causes below fall into eleven groups. Most real incidents mix two or three of them. Together they form the common causes of digital failures across modern information technology systems.
Werner Vogels, the CTO of Amazon, once said, “Everything fails all the time.” Accept that truth and you plan better. Each cause below shows you where to look first.
Network Connectivity and Communication Failures
Network connectivity problems top the list. Packet loss, high latency and slow DNS lookups all break transfers. Poor network architecture makes things worse. These network communication failures show up as network instability and connection errors. A rural link with 250ms delay can trigger timeouts again and again.
Server Overload and Performance Issues
Server performance issues appear when traffic spikes. Too many requests drain CPU and memory. Weak load balancing sends most work to one machine. The result is server overload and downtime. Good server management spreads the load before users feel any pain.
Client-Side Errors and Device Problems
Your own device can cause trouble. Old browsers, low memory and a bloated cache are common culprits. These client-side technical problems damage client-server communication. A phone with little free RAM may fail a large upload even on a perfect network.
Data Corruption and File Integrity Issues
Data integrity problems hide quietly. One missing byte can ruin a compressed file. Interrupted uploads, bad encoding and failing disks all damage data. Checksums such as SHA-256 protect file system integrity. When damage happens anyway, data corruption and file recovery become urgent. Sloppy data synchronization adds more conflicts.
Software Bugs and Compatibility Conflicts
Software compatibility issues often follow updates. An app built for an old API can break after a backend change. Plugin clashes and missing libraries add more pain. These software bugs and configuration errors call for careful software debugging. Smooth software deployment needs testing first.
Hardware and Operating System Failures
Hardware failures include dying drives, hot processors and unstable memory. Corrupt system files create hardware and operating system issues too. Weak operating system stability turns small faults into crashes. Backblaze publishes public hard drive statistics that show failure rates differ by model.
Security Threats and Access Control Problems
Security vulnerabilities and access failures can stop work cold. Expired tokens, wrong permissions and strict firewalls block valid requests. Malware can also disrupt normal processes. Solid access control management and strong cybersecurity protection reduce these risks without locking out real users.
Configuration Errors and System Mismanagement
Bad settings cause huge outages. One wrong value in system configuration can cut services off from each other. In October 2021, Facebook explained that a backbone router change disconnected its data centers, according to its own outage report. One small change broke a giant system.
Database Failures and Storage Limitations
Database errors include locked tables, slow queries and full disks. Weak database management lets small faults grow fast. Replication lag also leaves apps reading stale data. When storage runs out, writes fail and users see half-finished saves.
Third-Party Service and API Failures
Your system leans on outside services. Payment gateways, CDNs and cloud platforms can all fail. These cloud computing errors spread quickly through linked apps. Weak API communication without retries makes the damage worse. You can’t fix a vendor outage. You can plan for it.
Human Errors and Incorrect System Operations
People make mistakes. In 2017, an Amazon engineer mistyped a command during routine work and removed more servers than planned. Amazon explained the chain of events in its S3 outage summary. Guardrails and confirmation prompts stop a typo from becoming a headline.
What Are the Early Warning Signs of Tubefalire?
Early warning signs of system failure usually appear before the crash. Pages load slowly. Uploads stop at odd percentages. Retry messages pile up. Timeout errors jump without clear reason. Smart error detection catches these hints while the fix is still cheap.
Inconsistency is the loudest signal. A system that speeds up and slows down every few seconds is unstable. Treat that pattern as a system malfunction in progress. Strong system performance monitoring turns these hints into alerts you can act on.
How Does Tubefalire Affect Users, Businesses, and Digital Systems?
Users feel the pain first. They lose unsaved work. They see broken file versions. Trust drops fast when a favorite app keeps stalling. Even short Tubefalire errors can ruin a busy afternoon.
Businesses pay next. Support tickets rise and sales slip. Weak system reliability and availability also hurts the brand. The table below shows the three levels of impact.
| Group | Main Impact | Example |
| Users | Lost time and data | Upload fails at 87% |
| Businesses | Revenue and trust loss | Checkout page times out |
| Digital systems | Cascading faults | One slow service stalls many |
How to Diagnose Tubefalire Step by Step
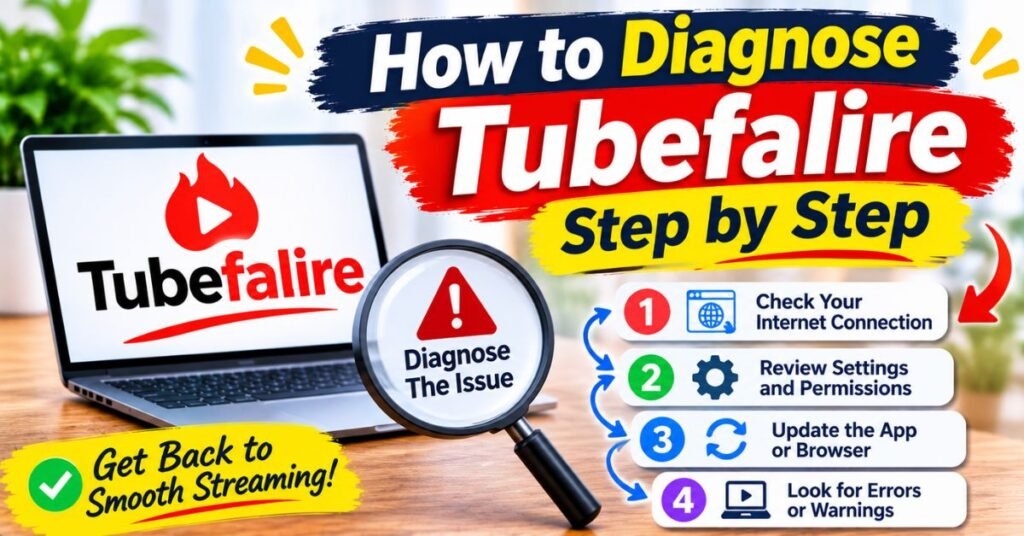
How to diagnose Tubefalire starts with one rule. Work from the outside in. Check the simplest layer first. Then move deeper. This habit supports clean root cause analysis and saves hours.
Follow the six steps below. They make up reliable technical troubleshooting. Each step rules out one layer of the chain.
Check Network Connectivity and Stability
Run a speed test first. Then measure latency and packet loss. Latency that stays above 100ms hints at trouble. Switch from Wi-Fi to a cable if you can. Stable links remove the most common network connectivity problems in minutes.
Identify Client-Side and Device Issues
Try another browser or device. Clear the cache and cookies. Turn off extensions for a moment. If the error vanishes, the fault sits on your side. This quick test isolates client-side technical problems from everything else.
Check Server Performance and Platform Health
Open the status page of the service. Read the error logs. Watch the response codes. The MDN guide to HTTP status codes explains what each family means. A run of 500-series codes points to server performance issues.
Inspect Data Integrity and Database Status
Compare file sizes before and after the transfer. Verify checksum hashes. Check disk space and query times in the database. Small mismatches reveal data integrity problems early. Healthy database management keeps these checks routine.
Review Software Logs and Error Messages
Logs tell the story. Look for repeated codes and odd timestamps. Match them to recent updates. This step is pure software debugging. It often links a failure to one exact change.
Identify Security and Configuration Problems
Check token expiry and user permissions. Review firewall rules. Compare current settings with the last working version. These checks catch security vulnerabilities and access failures along with sneaky software bugs and configuration errors.
Tubefalire Troubleshooting Guide: Common Problems and Solutions
How to fix Tubefalire errors depends on the symptom. Match what you see to the likely cause first. Then apply the matching fix. This approach keeps technical troubleshooting fast and calm.
Escalate when the fix fails twice. Contact technical support or the vendor with your logs ready. Clear notes speed up every case.
| Symptom | Likely Cause | Fix |
| Upload stops midway | Unstable network | Switch networks and retry |
| App freezes | Low memory | Close background apps |
| API timeout | Server overload | Retry later or scale up |
| Corrupted file | Interrupted transfer | Re-upload and verify hash |
| Login failure | Expired token | Refresh the session |
| Database timeout | Slow query or full disk | Optimize query and free space |
Why Do Tubefalire Errors Keep Coming Back?
Repeat failures point to deeper flaws. Weak design, missing backups and aging hardware are frequent roots. A lack of monitoring hides small faults until they grow. Quick patches treat the symptom and leave the cause alone.
Preventing recurring technical errors needs root fixes. Document each incident and track patterns. Then ask one question: what is the real trigger? That habit answers how to prevent recurring digital system failures better than any single tool.
How to Prevent Tubefalire in Digital Systems
Prevention beats repair every time. Small habits stop big outages. Strong IT system maintenance keeps small faults from spreading. It also supports long-term technology failure prevention.
These five habits form a simple base. They suit solo users and large teams alike. Together they improve digital infrastructure reliability.
Keep Software and Systems Updated
Updates close security holes and fix known bugs. Skip them and software compatibility issues pile up. Schedule patches during quiet hours. Test critical updates on a copy first. Regular IT system maintenance keeps every layer in sync.
Monitor Network and Server Performance
You can’t fix what you can’t see. Use automated system monitoring to track latency, errors and load. Alerts should fire before users complain. Steady system performance monitoring also helps with improving system performance over time.
Maintain Regular Data Backups
Backups turn disasters into delays. Follow the 3-2-1 rule: three copies, two media types and one copy offsite. Test your backup and restoration process often. A backup you never tested is only a hope.
Use Reliable Security and Access Controls
Give each person only the access they need. Rotate keys and tokens on a schedule. Pair this with strong cybersecurity protection. Careful access control management blocks threats without blocking honest work.
Test System Compatibility Before Deployment
Test every release against real devices and real data. Check API versions and library needs. Staged rollouts catch trouble early. Careful software deployment protects you from software compatibility issues on launch day.
How Organizations Can Prevent Tubefalire Through Better System Design
Smart design absorbs shocks. Load balancing spreads traffic across servers. Redundant systems take over when one part fails. Good IT infrastructure management also uses auto-scaling and clear runbooks. These steps raise fault tolerance across the whole stack.
Large providers use multi-region failover for extra safety. The AWS Reliability Pillar explains these design ideas in detail. Strong cloud-based infrastructure plus cloud infrastructure monitoring gives teams early visibility into trouble.
See Also: OnlyWorkMoods.com Review: 6 Powerful Facts You Should Know (2026)
What Is the Developer’s Role in Preventing Tubefalire?
Developers shape stability from the first line of code. They validate inputs and write clear error messages. They add retry logic with exponential backoff. These developer strategies for error prevention keep small faults from cascading.
A good system slows down safely instead of crashing. Developers can also build graceful fallbacks for API communication. Google’s free Site Reliability Engineering book offers deep guidance. Practical lessons there answer how developers can prevent software failures.
How Performance Testing Helps Prevent Tubefalire
Testing exposes weak spots before users do. Load tests copy normal traffic. Stress tests push systems past their limits. Latency tests find slow routes. Each test supports performance optimization and better application performance.
Imagine a simulated crowd of 10,000 users. A hidden bottleneck in the database may suddenly appear. You fix it on a quiet Tuesday instead of during a sale. That is technology failure prevention in action.
Security Risks That Can Trigger Tubefalire
Security tools sometimes block honest traffic. Expired sessions interrupt work. Overstrict firewalls cut off APIs. Malware can also drain resources and corrupt files. These security vulnerabilities and access failures can look just like a network fault.
Balance is the goal. Tight cybersecurity protection must still allow smooth sessions. Review rules often and log every block. Clear logs make root cause analysis much faster.
Advanced Recovery Strategies When Tubefalire Persists
Some failures resist simple fixes. Start with deep log review. Roll back the latest update if timing matches. Restart isolated services one at a time. These system recovery methods limit the blast radius.
Restore from backups when data is damaged. Then confirm file system integrity before going live again. The NIST guide on contingency planning supports solid disaster recovery planning. A tested disaster recovery plan cuts panic and downtime.
How Cloud Computing Affects Tubefalire and System Reliability
Cloud platforms add flexibility. You can scale up in minutes. Yet they also add complexity. Dependencies spread across many services. Cloud computing errors can start in one region and travel far.
Good design limits that spread. Use several zones and test failover often. Track health with cloud infrastructure monitoring. That answers how cloud computing helps prevent digital failures when teams plan well. It also supports system reliability and availability.
The Future of Tubefalire Prevention and Digital Reliability
Systems are growing smarter. AI tools now spot odd patterns before humans can. Predictive models flag parts that may fail soon. Self-healing platforms restart broken services alone. These advances will reshape digital infrastructure reliability.
Edge computing also cuts delay by moving work closer to users. Expect better error detection and faster system recovery methods. The goal is simple. Fewer surprises and shorter outages.
See Also: Research Dossier for Target Company: Complete Guide, Free Template & AI Workflow (2026)
Best Practices for Managing and Preventing Tubefalire
Expect failure and prepare for it. That mindset beats any single tool. Fix root causes instead of symptoms. Monitor everything in real time. Review every incident and share the lessons with your team.
The table below sums up the key habits. Use it as a quick checklist. Each habit supports best ways to improve digital system reliability.
| Habit | Main Benefit |
| Update on schedule | Fewer compatibility conflicts |
| Monitor continuously | Faster error detection |
| Back up and test restores | Safer recovery |
| Limit access rights | Lower security risk |
| Test before release | Fewer launch failures |
| Review every incident | Fewer repeat errors |
Frequently Asked Questions
These short answers cover the most common questions. Each one gives the key point first. Use them as a fast reference.
Read the full sections above for deeper detail. The FAQ simply sums up the main ideas.
What Does Tubefalire Mean?
The Tubefalire meaning centers on a layered breakdown in a digital system. Data stops flowing before a task finishes. It isn’t an official technical term. It describes a real pattern of digital system failures that IT teams see daily.
What Are the Main Causes of Tubefalire?
What causes Tubefalire errors? The main Tubefalire causes include network faults, server overload and device limits. Data damage, software conflicts and hardware wear also play a role. Security rules, bad settings, database trouble, vendor outages and human mistakes complete the list.
Is Tubefalire Related to Network Problems?
Yes. Network connectivity problems are the most common trigger. Packet loss and high latency stall transfers quickly. Still, they aren’t the only source. Servers, devices and software compatibility issues can cause the same symptoms.
How Can You Fix Tubefalire Errors?
Start with the network. Then test your device and check server health. Next inspect data and logs. Follow the digital system troubleshooting steps in order. This method shows how to troubleshoot Tubefalire step by step without guesswork.
Can Tubefalire Cause Data Loss?
Yes. Interrupted uploads and failed syncs can leave damaged or partial files. That is why data corruption and file recovery matter. Keep tested backups and verify checksums. These steps also show how data corruption affects system performance.
How Can Developers Prevent Tubefalire?
Developers can validate inputs and add retries with backoff. They can write clear errors and test under heavy load. Careful software debugging and staged releases help too. These habits form strong developer strategies for error prevention.
Final Thoughts on Tubefalire
Tubefalire isn’t random chaos. It signals that something in the chain needs attention. Network faults, server strain, device limits, bad data and human slips all feed it. When you know the Tubefalire causes, you stop guessing.
Take action today. Check your backups. Turn on system performance monitoring. Update your software. Small steps build strong digital infrastructure reliability. Your next upload may finish at 100%.
Arslan Rafi is a writer and language enthusiast who creates easy-to-understand content about slang, expressions, words, and their meanings. His work focuses on explaining regional and modern language in a clear, engaging way, helping readers understand how words and phrases are used in everyday conversation.